Why Cloud Cost Keeps Rising While Business Usage Stays Flat
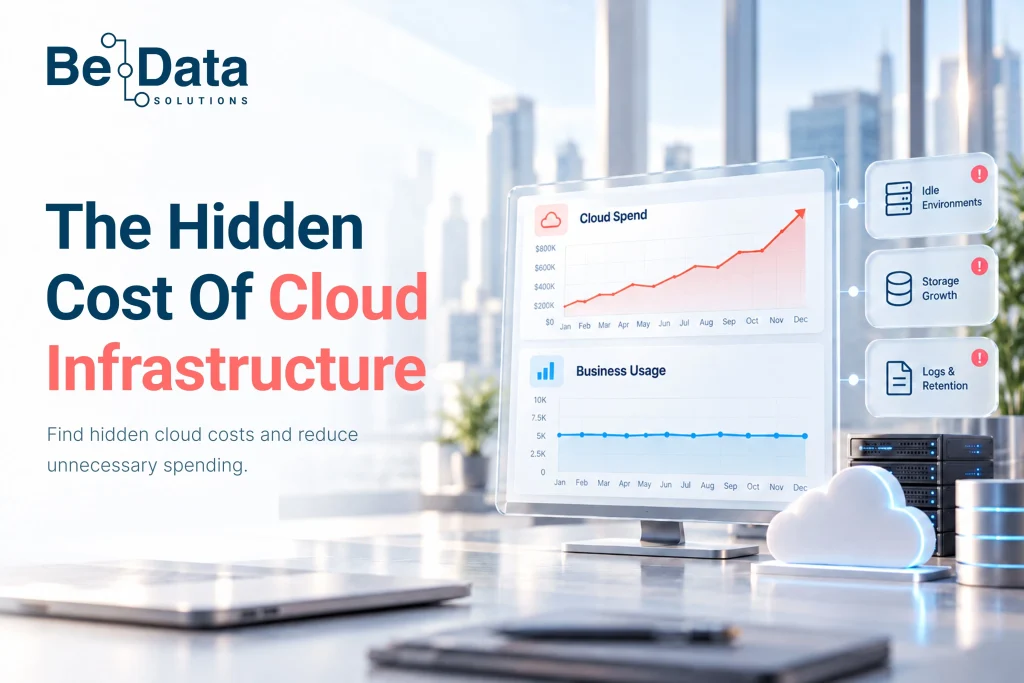
Your customers are the same as last year. Orders are about the same. No big new product was launched. Still, the cloud bill is higher than last quarter, and last quarter it was higher than the one before. If this sounds familiar, you are not alone, and in most cases the reason is not business growth. The cause sits inside the system itself. Servers were built too big, environments were left running, and nobody owns the bill. This guide goes through eight places where cloud money usually leaks, shows how to check each one, and explains how to fix it without slowing down your engineers.
The bill goes up and nobody can say why
Here is a meeting that happens in many companies. Finance sees that the cloud invoice is 12% higher than last quarter and asks the CTO what changed. The CTO says the platform is bigger now, or that a few new services were added. Finance asks a fair question. Orders are flat, so why is the bill not flat? After that the room goes quiet, because nobody has the full answer.
This is not a small problem. Flexera’s 2026 State of the Cloud report, based on a survey of more than 750 cloud decision makers, found that organisations estimate 29% of their infrastructure and platform spend is wasted. A year earlier the figure was 27%, and this was the first rise after five years of improvement. These numbers are self-estimates and not audits, so please take them as a rough guide. But the direction is clear. Even companies that have worked on cost for years are finding that the waste comes back.
One reason is simple. Cloud makes it very easy to start spending and not so easy to stop. A developer can create a test server in five minutes. To switch it off, someone has to remember that it exists, know who owns it, and be sure that nothing depends on it. Most of the time nobody does this work, and the server runs for months.
First, check if the demand is real
Before looking for waste, it is fair to ask if the bill has grown for a reason outside your control. A few things can push the invoice up even when your team did nothing wrong. Prices change. A discount, a credit or a commitment may have expired. If you pay in dollars and report in pounds, the exchange rate can move the number. And sometimes the demand is real, but it does not show in customer numbers, for example when your data grows faster than your user count.
That last point matters more than people think. Business usage and system usage are two different things. Your customers may be flat, but your data is not. Every day more logs, more backups, more snapshots and more table rows are added. Storage does not go down by itself. So a business that looks flat from outside can still have a system that becomes heavier every month.
A cloud bill can keep growing even when the business is not growing at all.
The easiest way to separate real demand from waste is to put one business number next to the bill. It can be orders, active users or transactions, whatever your business counts. When you look at cost per order instead of total cost, the story becomes clear. The table below shows what some common patterns usually mean.
| What you see in the bill | What it usually means |
|---|---|
| Cost rises slowly every month, even when traffic is flat | Data is piling up: storage, logs, backups, snapshots |
| Cost jumps on one particular date | A release, a new service, a setting change, or an expired discount |
| Night and weekend cost is almost the same as working-hour cost | Environments are running 24/7 and nobody uses them outside office hours |
| Cost per order or per active user is going up | Workloads have become less efficient, even if demand is the same |
| One service (database, logging, data warehouse) grows faster than the rest | A query, logging or pipeline problem in that area |
| A large part of the bill has no owner or tag | Nobody is accountable, so the waste stays hidden |
None of these patterns proves the cause by itself. But they tell you where to look first, and that saves a lot of time.
Oversized compute resources
This is the most common leak, and the easiest to understand. When a server is created, the team has to choose a size. Nobody knows exactly how much traffic will come, so they choose a bigger size to be safe. The system goes live, it works well, and nobody comes back later to ask if the size was right.
There is a reason behind this behaviour. A slow application is visible at once. People complain, and the CTO gets a call at night. A big bill is not visible until next month, and it is spread over many line items. So teams protect themselves from the first problem and accept the second one.
To check, look at two to four weeks of CPU and memory use for your biggest servers. Look at memory too, because many teams watch only CPU. If a server stays below 30 or 40 percent most of the time, it is a candidate for a smaller size. AWS, Azure and Google Cloud all have free tools that give sizing suggestions, such as AWS Compute Optimizer, Azure Advisor and the Google Cloud recommender. Use the suggestions as a starting point and not as an order.
In Kubernetes, the same problem sits in a different place. Pods are given large CPU and memory requests, the cluster adds nodes to fit them, and the nodes stay mostly empty. The bill shows the nodes, but the real issue is in the requests.
Go down one size at a time, watch the system for a week, and then decide the next step. One more point, and it is important. Right-size first, and only then buy reserved instances or savings plans. If you buy a one-year or three-year commitment for a server that is too big, you have locked in the waste at a lower price. It is still waste.
Let us take a simple example. These numbers are only for illustration, and your own rates will be different. A team runs ten servers at £300 per month each. Six of them can move one size down, and the smaller size costs about half. That saves £150 on each of the six servers, which is £900 a month or £10,800 a year. The work takes a few days, and customers see no change.
Idle development environments
Production runs all day because customers use it all day. Development, testing, staging and demo environments do not need that. But in most companies they run 24 hours a day, seven days a week.
The numbers are easy. A week has 168 hours. A team that works 10 hours a day for five days uses an environment for about 50 hours. For the other 118 hours, which is about 70% of the week, the environment is running for nobody. If you switch it off at night and on weekends, you can cut roughly 70% of its compute cost. Disks and storage still cost money while a server is stopped, so the saving is on compute and not on the whole environment.
The second problem is environments that nobody uses at all. A proof of concept for a client demo, a test setup for a project that finished last year, a staging copy that one engineer made for a bug and then moved to another team. These are often the most expensive ones, because they were built as a full copy of production.
What helps is simple. Set automatic start and stop schedules for non-production, using the scheduling tools from your cloud provider or a small script. Give every temporary environment an expiry date in its tags, and delete it when the date comes, unless the owner asks for more time. Create short-lived environments for each feature branch and remove them after the merge. And once a month, send the list of non-production environments to their owners and ask one question: do you still need this?
A small note on schedules. If your team works across time zones, for example between the UK and South Asia, the working window is longer than one office day. So set the schedule for each team, and do not use one rule for the whole company.
Poor storage-retention policies
Storage looks cheap when you see the price per GB, so almost nobody checks it. But it has one special feature. It only grows. Old backups, snapshots of servers that were deleted long ago, files exported for a one-time analysis, disks left behind when a server was removed, old versions of files in buckets where versioning is on. After two or three years this becomes a big part of the bill.
The fix starts with a decision, and the decision is not technical. For each type of data, someone must say how long it is really needed, for business reasons, for legal or audit reasons, and for recovery. Backups should match your recovery needs, and not be kept forever. Once the decision is made, lifecycle rules can do the work. They move data to cheaper storage after a set number of days and delete it after a set period.
Retention is not only a cost topic. Under UK GDPR, personal data should not be kept longer than necessary, so a clear retention policy also helps with compliance. At the same time, be careful before you delete anything. Some data must be kept for audit or legal reasons, so always check with the data owner first.
One more point about cheaper tiers. Colder storage costs less to keep, but many tiers charge extra when you read the data, and some charge a fee if you delete before a minimum period. So move the data that you rarely open, and keep the data your team uses every week on the normal tier.
To check, list your biggest storage containers and see when they were last accessed. Look for disks that are not attached to any server. Count the snapshots older than 90 days. These three checks alone usually find something.
Inefficient database queries
When a database becomes slow or its CPU goes high, the common answer is to move to a bigger instance. It works for a few weeks, and then the extra cost stays forever. Many times the real reason is a small number of queries that are written or indexed badly.
The usual problems are simple. A missing index, so the database reads the whole table to find a few rows. A query that asks for every column when the screen needs only two. The same query called thousands of times, once for each row, instead of one time for all rows. Heavy reports running on the live production database during working hours.
In pay-per-use data warehouses the link to money is even more direct, because the bill depends on how much data each query reads or how long the warehouse stays on. A bad query is paid for again every time it runs.
Think about a dashboard that refreshes every five minutes, and each refresh reads a full large table. That is 288 reads a day and about 8,600 a month. If nobody opens the dashboard at night, most of those reads are waste.
To fix this, turn on the slow-query log or the query insights tool of your database. Sort the queries by total time or total data read, and fix the top ten first. Often that is enough. Add the missing indexes. Split very large tables by date, so that queries read only the part they need. Cache the results for dashboards, and refresh them as often as people really need the data, not as often as the system allows. Move reporting to a read replica or a separate warehouse so that it does not fight with the live application. And before anyone approves a bigger database, ask for the query analysis first.
Excessive logging
Logs are very useful when something breaks. But many logging tools charge by the amount of data you send in, so every extra line has a price.
The causes are usually ordinary. Debug logging that was switched on to find a bug and never switched off. Full request and response bodies written for every call. Health checks that write a line every few seconds from every server. The same log stored in two or three different tools. And all logs kept in the expensive searchable tier for a full year, when people only search the last two weeks.
On some platforms the default setting is to keep logs forever unless someone sets a retention period. So if nobody touched the setting, the old logs are still there, and still being paid for.
You do not need to stop logging. Set the log level by environment, with detailed logs only where they are needed. Sample the routine, high-volume logs instead of saving every line. Drop the health-check noise. Keep the recent logs, say the last 7 to 30 days, in the searchable tool, and send older logs to cheap storage. Set a retention period on every log group. Be careful with security and audit logs, because some of them must be kept for a fixed period, so check the requirement before you reduce them.
Weak autoscaling
Autoscaling is meant to prevent all of this, but it helps only when it is set well. In many systems it is switched on once and then forgotten.
The common mistakes are these. The minimum number of instances is set high just in case, so the system never really scales down. The system scales up fast but scales down slowly, or not at all, because the cool-down time is too long. The rule uses CPU while the real limit is memory, queue length or number of requests, so scaling happens at the wrong time. Traffic follows a clear pattern, like office hours, month-end or a weekly campaign, but nobody has set a schedule for it. In Kubernetes, nodes do not scale down because some pods cannot be moved or have very large requests.
A simple check is to open a graph of capacity and actual load for one week. If the capacity line stays flat while the load goes up and down, autoscaling is not doing its job. You are paying for peak capacity all the time.
To fix it, lower the minimum based on real data, and do it slowly. Scale on the metric that matches the real bottleneck. Add scheduled scaling for patterns you already know. And test the scale-down path as carefully as the scale-up path, because the savings come from scaling down.
Uncontrolled data-processing workloads
For companies with a lot of data, this is often the biggest hidden cost, and the hardest to see. Pipelines and batch jobs run on a schedule. Once they work, nobody looks at them again.
When you start looking, you often find things like these. A job runs every hour, but the report built from it is read once a day. A pipeline reloads the full table each time instead of only the new rows. Two teams built two pipelines that produce almost the same output. A pipeline made by an engineer who left a year ago is still running. A failed job retries again and again and runs for days. Test runs use full production data. A machine learning training job on an expensive GPU machine is left running after the training has finished. Data moves between regions or out to the internet, and the transfer charges grow without anyone noticing.
For each pipeline, ask four questions. Who uses the output? How often do they really need it? What does one run cost? Who owns it? Many pipelines cannot answer even the first question.
Then fix things in order. Change full reloads to incremental loads. Set time limits and retry limits on every job, so that a stuck job cannot run for days. Put a maximum size on clusters. Run non-urgent batch jobs that can safely restart on cheaper spot or preemptible capacity. Keep data and compute in the same region when possible. Track the cost of each pipeline run, so a sudden jump is visible. And give every experiment a switch-off date.
Ownership, tagging and budgeting
All the leaks above have one thing in common. They stay alive because nobody owns them. The cloud invoice reaches finance as one large number. The engineers who create the resources never see that number, and the finance team who see it cannot tell which resource caused it. The fix is to connect these two sides.
Start with tags. Tags are small labels on every resource, and they are the way a bill becomes readable. A small, fixed set is enough.
| Tag | What it tells you | Example |
|---|---|---|
| Owner | Which person or team is responsible | payments-team |
| Environment | Production, staging, development or test | dev |
| Product or project | Which product the cost belongs to | checkout |
| Cost centre | Which budget it should be charged to | CC-2041 |
| Expiry date | When a temporary resource should be deleted | 2026-12-31 |
A tagging rule works only if it is enforced when the resource is created. Most cloud platforms can block the creation of resources that do not have the required tags, so use this feature and do not depend on people’s memory. Then track the share of untagged spend as one number, and bring it down every month.
Next are budgets. One budget for the whole account is not enough, because it only tells you that something went wrong and not where. Set budgets for each team or product, with alerts at points such as 50%, 80% and 100%. Turn on the anomaly detection that the cloud providers already offer, so that a sudden jump is noticed in days and not at the end of the month.
Then think about how you share the information. A good first step is showback. Send every team its own cost report each month, without charging them yet. In many companies, behaviour changes just because people can see the number. Charging teams for their usage can come later, when the data is trusted.
The last piece is a number that finance and engineering can both read, and that is unit cost. It can be cost per order, per active user or per transaction. Total cost can go up and still be healthy if the cost per unit goes down. It can also look flat while the unit cost gets worse. Put this number next to the total in your monthly review.
And someone has to own the topic. You do not need a large FinOps department for this. One named person, plus a monthly 30-minute review with the engineering lead and a finance partner, is enough to start.
The eight areas at a glance
| Area | Where to look first | First action |
|---|---|---|
| Oversized compute | Servers and nodes with low CPU and memory use over 2 to 4 weeks | Move down one size, then review commitments |
| Idle development environments | Non-production cost at night and on weekends | Automatic start and stop, plus expiry dates |
| Storage retention | Biggest buckets, old snapshots, unattached disks | Lifecycle rules based on agreed retention |
| Database queries | Slowest and most data-heavy queries | Fix the top ten queries before adding capacity |
| Logging | Log volume by service and retention settings | Set log levels and retention, archive old logs |
| Autoscaling | Capacity against load over one week | Lower minimums, scale on the right metric |
| Data processing | Job schedules, retries and full reloads | Incremental loads, time limits, cost per run |
| Ownership | Untagged spend and budgets per team | Enforced tags, team budgets, monthly review |
Where to start: the first 30 days
The order matters. Start with changes that carry almost no risk for customers, such as idle and unused resources. After that, move to resizing. Redesign work comes last.
In the first week, break down the bill by service, account and tag. Find the untagged spend. Choose one business number and calculate the cost per unit.
In the second week, do the safe clean-up. Switch off idle environments, delete unattached disks and old snapshots, and set retention on logs.
In the third week, resize the biggest compute resources and review the ten worst database queries.
In the fourth week, set the tagging rule, the team budgets and the alerts. Then hold the first monthly cost review.
After that, repeat every month. Cloud cost is not a one-time project. Systems change every week, so the review has to continue.
Final thoughts
A rising cloud bill with flat usage is not a mystery. In most cases it is a small number of known causes, running quietly and without an owner. The companies that keep their bill under control are not the ones with the cleverest tools. They are the ones where somebody looks at the numbers every month and knows who to ask when a number looks wrong.
If you would like a second pair of eyes, Be Data Solutions can review your cloud and infrastructure cost with you. We work across Azure, AWS and Google Cloud, and we look at three things together: your bill, your architecture and who owns what. You get a clear list of what to switch off, what to resize, what to redesign, and what each change is worth.
Request a cloud and infrastructure cost review →
About Be Data Solutions: Be Data Solutions is a data engineering, software engineering, analytics, and ML & AI agency headquartered in London, with an engineering hub in Dhaka. ISO 9001, ISO/IEC 27001 and ISO/IEC 42001 certified. We work with scale-ups, enterprises, and public sector organisations across retail, healthcare, media, manufacturing, and professional services.